GPT-5.6 Luna vs DeepSeek V4: Budget Flagship vs Open-Weight Price (2026)
GPT-5.6 Luna leads the AA Intelligence Index 51 to 44; only DeepSeek is charted on coding. After OpenAI's price cut Luna undercuts DeepSeek V4 on input. A split verdict.
Feature Comparison
| Feature | GPT-5.6 Luna | DeepSeek V4 |
|---|---|---|
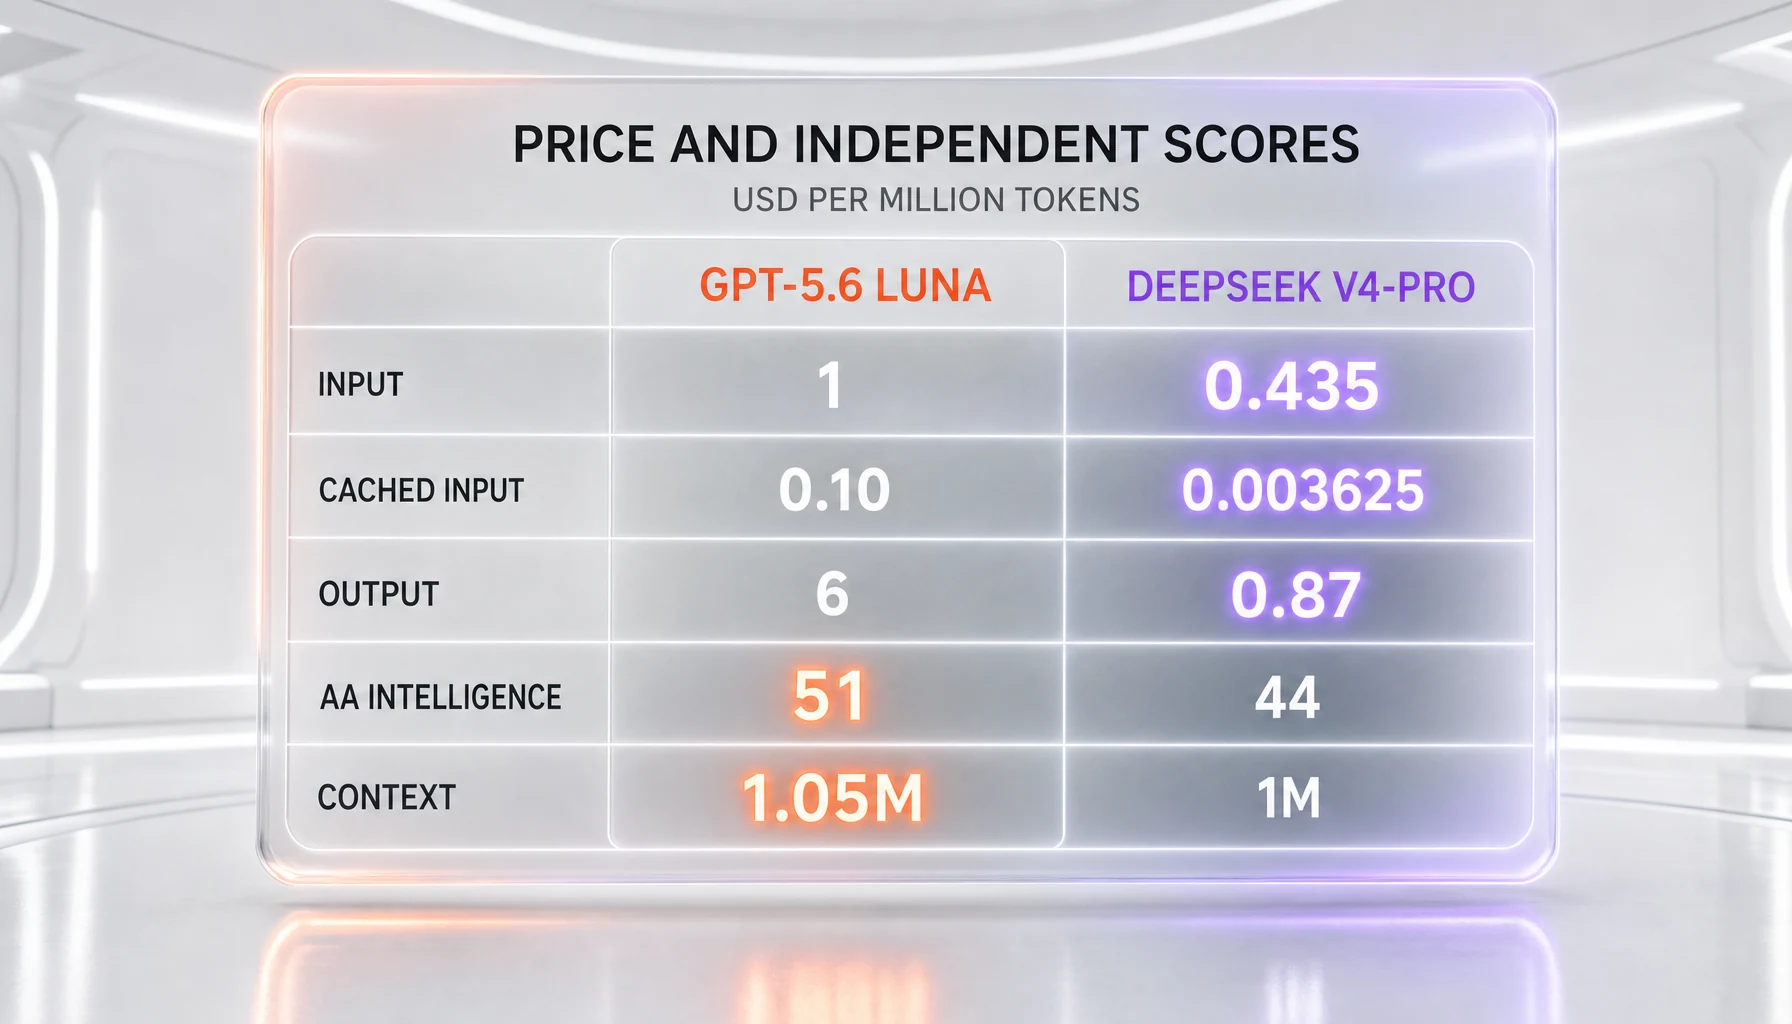
| AA Intelligence Index (Artificial Analysis v4.1, same evaluator) | 51 | 44 (V4-Pro, max reasoning) |
| AA Coding Agent Index v1.3 (Artificial Analysis, read August 2, 2026) | 51.42 (Codex harness, high effort); 58.66 at max | 31.44 (Claude Code harness, high effort) |
| Input price (per million tokens) | 0.20 dollars | Off-peak V4-Pro 0.66, V4-Flash 0.22 dollars (1.32 / 0.44 at peak) |
| Output price (per million tokens) | 1.20 dollars | Off-peak V4-Pro 1.98, V4-Flash 0.66 dollars (3.96 / 1.32 at peak) |
| Cached input (per million tokens) | 0.02 dollars | Off-peak V4-Pro 0.022, V4-Flash 0.007 dollars (0.044 / 0.014 at peak) |
| Context window | 1,050,000 tokens | 1,000,000 tokens |
| Max output tokens | 128,000 tokens | 384,000 tokens |
| Weights and license | Closed (API, ChatGPT, Codex) | Open weights, MIT license |
| Self-hostable | No | Yes, including Huawei Ascend |
| Modality | Text and image input | Text only |
| SWE-bench Verified (independent) | Not yet charted (too new) | Not independently charted (80.6 percent self-reported) |
| Western data residency and compliance | US-hosted, regional residency endpoints | China-hosted API, or self-host anywhere |
Pricing Comparison
GPT-5.6 Luna
DeepSeek V4
Detailed Comparison
GPT-5.6 Luna and DeepSeek V4 are the two large language models compared here, and this is the tightest price matchup in the whole DeepSeek V4 series. GPT-5.6 Luna is OpenAI's budget, high-volume capability tier, generally available July 9, 2026, priced at 0.20 dollars per million input tokens and 1.20 dollars per million output tokens after OpenAI's July 30, 2026 price cut. DeepSeek V4 is DeepSeek's open-weight Chinese flagship, shipped under an MIT license on Hugging Face, with a hosted V4-Pro tier at 0.66 dollars input and 1.98 dollars output per million tokens off-peak (1.32 and 3.96 at peak) and an even cheaper V4-Flash tier. On the one independent evaluator that scores both models the same way, Artificial Analysis, GPT-5.6 Luna leads the Intelligence Index 51 to 44 for DeepSeek V4-Pro, and it leads on the AA Coding Agent Index v1.3 as well, 51.42 through the Codex harness at high reasoning effort against 31.44 for DeepSeek V4 Pro through the Claude Code harness at the same effort. DeepSeek V4 is about 1.4 times cheaper on output but about 2.2 times more expensive on input since that cut, ships open weights you can self-host for full data sovereignty, and edges Luna on maximum output length. This is a split verdict, not a single winner. Best for measured intelligence, image input, and Western data residency: GPT-5.6 Luna. Best for the lowest price, open weights, and self-hosting: DeepSeek V4.
Quick Verdict
This is a split verdict by use case, not a single overall winner — and it is the narrowest price gap in the entire DeepSeek V4 series. We ran both models side-by-side through their hosted APIs, pulled the pricing directly from each vendor's own pages, and added our own hands-on observations from using both on coding and reasoning prompts. We have not run weeks of controlled, identical-task benchmarking of the two against each other, so where we lean on numbers we attribute them to their source. The honest summary is that these two models are not fighting for exactly the same buyer — but because Luna is OpenAI's cheapest tier, the usual chasm between a managed US flagship and an open Chinese challenger shrinks to something close to a rounding error on input. Here is the short version.
- Best for measured intelligence: GPT-5.6 Luna. On the Artificial Analysis Intelligence Index — the one composite that scores both models with the same battery — Luna sits at 51 while DeepSeek V4-Pro in its maximum reasoning mode scores 44, a clear 7-point lead, the smallest capability gap of any OpenAI tier against DeepSeek but a real one.
- Best for measured coding: GPT-5.6 Luna. Artificial Analysis charts it at 51.42 on the Coding Agent Index v1.3, through the Codex harness at high reasoning effort, against 31.44 for DeepSeek V4 Pro through the Claude Code harness at the same effort — 19.98 points clear, in different harnesses. Luna's ceiling on that board is 58.66, at max effort, and it ships a full agentic tool stack — function calling, web search, file search, code interpreter, computer use, and MCP — on by default.
- Best for cost: split, and the margins collapsed on July 30, 2026. V4-Flash output at 0.66 dollars per million tokens off-peak (1.32 at peak) is about 1.8 times cheaper than Luna at 1.20 dollars, but V4-Pro output at 1.98 dollars off-peak now costs about 1.65 times more than Luna, where it used to be cheaper. On input Luna leads outright: at 0.20 dollars it is about 3.3 times cheaper than V4-Pro at 0.66 dollars, and it now undercuts V4-Flash at 0.22 dollars as well.
- Best for open weights and self-hosting: DeepSeek V4. The weights ship under an MIT license and run on your own hardware, including Huawei Ascend chips. Luna is closed and API-only.
- Best for Western data residency and compliance: GPT-5.6 Luna. It is hosted by OpenAI in the US with regional data-residency endpoints. DeepSeek's hosted API runs in China, which is a non-starter for many regulated buyers unless they self-host the open weights.
Bottom line: if you want more measured intelligence, image input, or US-hosted compliance, pick GPT-5.6 Luna. If you want to own your weights or need to self-host for data sovereignty, DeepSeek V4 gives you frontier-adjacent quality on a rate card that still wins on standard output. We did not crown a single winner because the two models optimize for different things — but after OpenAI's July 30, 2026 price cut the price penalty for staying managed has gone negative on input, so the trade is a genuine judgment call rather than a foregone conclusion.
At a Glance
Before the detail, here is the side-by-side that frames everything below. All pricing in this table was fetched directly from each vendor's pricing page in July 2026. All benchmark figures are attributed to their source, and independent scores are kept strictly separate from vendor-reported ones.
| Dimension | GPT-5.6 Luna | DeepSeek V4 |
|---|---|---|
| Vendor and origin | OpenAI (US) | DeepSeek (China) |
| License | Closed — API, ChatGPT, and Codex only | Open weights, MIT license |
| Available | July 9, 2026 (general availability) | April 24, 2026 |
| Input price (per million tokens) | 0.20 dollars (verified) | Off-peak Pro 0.66, Flash 0.22 dollars (1.32 and 0.44 at peak, verified) |
| Output price (per million tokens) | 1.20 dollars (verified) | Off-peak Pro 1.98, Flash 0.66 dollars (3.96 and 1.32 at peak, verified) |
| Cached input (per million tokens) | 0.02 dollars (verified) | Off-peak Pro 0.022, Flash 0.007 dollars (0.044 and 0.014 at peak, verified) |
| Context window | 1,050,000 tokens (verified) | 1,000,000 tokens (verified) |
| Max output tokens | 128,000 tokens | 384,000 tokens |
| AA Intelligence Index | 51 (Artificial Analysis v4.1) | 44 for V4-Pro max reasoning (Artificial Analysis v4.1) |
| AA Coding Agent Index v1.3 (read August 2, 2026) | 51.42 (Codex harness, high effort); 58.66 at max | 31.44 (Claude Code harness, high effort) |
| Modality | Text and image input, text output | Text only |
| Self-hostable | No | Yes, including Huawei Ascend chips |
| Data residency | US, plus regional residency endpoints | China-hosted API, or self-host anywhere |
Overview of Each Model
GPT-5.6 Luna
GPT-5.6 Luna is the budget, high-volume tier of OpenAI's GPT-5.6 generation, which became generally available on July 9, 2026 across ChatGPT, Codex, and the API. In the new naming scheme the number is the generation and the names Sol, Terra, and Luna are durable capability tiers rather than model sizes: Luna is the economy option built for the highest-throughput, most cost-sensitive work — bulk classification, extraction, routing, retrieval, and cheap agent loops — while still carrying the generation's reasoning ability. It ships a 1,050,000-token context window with up to 128K output tokens, a February 16, 2026 knowledge cutoff, and accepts text and image input while producing text output. On independent benchmarks it is the stronger model in this matchup: it scores 51 on the Artificial Analysis Intelligence Index and 51.42 on the AA Coding Agent Index v1.3, through the Codex harness at high reasoning effort. It ships the same agentic tool stack as the rest of the generation, all on by default — function calling, structured outputs, web search, file search, code interpreter, a hosted shell, computer use, and MCP — alongside a reasoning-effort scale that runs from low through xhigh and adds a new max level. Pricing is 0.20 dollars per million input tokens and 1.20 dollars per million output after OpenAI's July 30, 2026 price cut, with prompt caching at a 90 percent discount (0.02 dollars per million cached input tokens) and a Batch API at half price for asynchronous work. It is closed and available only through OpenAI's surfaces. In our hands-on use, the standout is how much of the generation's reliability and tool orchestration survives at the cheapest rate card OpenAI offers. For the full breakdown, see our GPT-5.6 Luna review; if you need more measured capability, we also cover the mid-tier GPT-5.6 Terra and the top-tier GPT-5.6 Sol.
DeepSeek V4
DeepSeek V4 is the Chinese open-weight flagship, shipped April 24, 2026 in two sizes: V4-Pro, a 1.6-trillion-parameter mixture-of-experts model with about 49 billion parameters active per token, and V4-Flash, a 284-billion-parameter model with about 13 billion active. Both carry a 1,000,000-token context window with up to 384K tokens of output, and both ship under an MIT license that permits free commercial use, redistribution, and modification of the weights — although the training code and data recipe are not released, so this is open weights rather than fully open source. Artificial Analysis scores V4-Pro at 44 on its Intelligence Index in maximum reasoning mode, well above the median for open-weight models of similar size, and DeepSeek separately reports 80.6 percent on SWE-bench Verified — a self-reported figure on its own harness, not an independently charted one. The architecture is genuinely novel rather than just bigger: a Hybrid Attention design combining Compressed Sparse Attention at four-times compression with Heavily Compressed Attention at 128-times compression cuts inference compute and KV-cache footprint sharply, and three built-in thinking modes — Non-Think, Think High, and Think Max — let you dial cost against quality per request. It is text only, the hosted API is OpenAI-compatible, and it runs day one on Huawei Ascend hardware. The headline, though, is price: V4-Pro output sits at 1.98 dollars per million tokens off-peak (3.96 at peak) and V4-Flash at 0.66 dollars (1.32 at peak). Our full DeepSeek V4 review covers the architecture and licensing in more depth.
Pricing Compared
Pricing is still where the two models diverge most — but this is the matchup where the gap is narrowest in the whole series, because Luna is deliberately the cheapest OpenAI tier rather than a premium one. We fetched every number below directly from each vendor's pricing page in July 2026.
| Tier | Input (per million tokens) | Output (per million tokens) | Cached input (per million tokens) |
|---|---|---|---|
| GPT-5.6 Luna (standard) | 0.20 dollars | 1.20 dollars | 0.02 dollars |
| GPT-5.6 Luna (Batch API, 50 percent off) | 0.10 dollars | 0.60 dollars | — |
| DeepSeek V4-Pro (off-peak) | 0.66 dollars | 1.98 dollars | 0.022 dollars |
| DeepSeek V4-Flash (off-peak) | 0.22 dollars | 0.66 dollars | 0.007 dollars |
Run the arithmetic and the picture has changed shape. On output tokens — the comparison most people care about, because output dominates real agentic spend — Luna at 1.20 dollars is now about 1.65 times cheaper than V4-Pro at 1.98 dollars off-peak, having been the more expensive of the two before August 16, 2026, and about 1.8 times the cost of V4-Flash at 0.66 dollars. On input tokens Luna leads both DeepSeek tiers: at 0.20 dollars it is about 3.3 times cheaper than V4-Pro at 0.66 dollars, and it now edges out V4-Flash at 0.22 dollars, which used to undercut it. Those output multiples are the smallest of any OpenAI tier against DeepSeek by a wide margin: the top-tier Sol runs at 20 dollars output, some 10 times V4-Pro off-peak, and the mid-tier Terra at 12 dollars is about 6 times, so choosing Luna now collapses nearly all of the distance to DeepSeek's rate card. Luna's prompt caching is cheap by frontier standards at 0.02 dollars per million cached input tokens, and since August 16, 2026 it is marginally cheaper than DeepSeek's V4-Pro cache-hit input at 0.022 dollars off-peak; only V4-Flash, at 0.007 dollars, still undercuts it, by about 2.9 times.
The most telling number is what happens with Luna's Batch API. Its 50 percent discount brings Luna to 0.10 dollars input and 0.60 dollars output, which puts input about 6.6 times below V4-Pro off-peak and output about 3.3 times below it. At Batch pricing a managed, US-hosted frontier model is now cheaper than the open Chinese one on both lines. That is a genuinely different conversation from the order-of-magnitude gaps you see with the premium tiers. Two nuances worth flagging honestly. First, the DeepSeek V4-Pro rates above are the off-peak tier of a two-tier grid that replaced flat pricing on August 16, 2026; they are not a discount, since every off-peak rate sits between 1.52 and 6.07 times the flat rate it replaced. Peak hours (01:00 to 04:00 and 06:00 to 10:00 UTC, Monday through Friday) bill at double. V4-Flash is the cheaper tier for lighter, high-volume work. Both are pay-per-token on a hosted API, and both were read straight off DeepSeek's pricing page. Second, a self-hosted DeepSeek deployment is not free: running V4-Pro yourself in full precision requires enterprise GPU clusters, and even V4-Flash needs INT4 or INT8 quantization to fit on a single high-end consumer card. The open weights buy you control and remove per-token billing, but they shift cost into hardware and operations. For most teams the hosted DeepSeek API is the relevant comparison, and there DeepSeek is still cheaper on standard output — but no longer on input, and no longer at all once Luna's Batch discount applies.
Benchmarks Compared
Benchmarks across two different labs are a minefield, because vendors pick favorable evaluations and report them their own way. We discipline this by leaning on the one independent evaluator that scores both models the same way — Artificial Analysis — and by treating vendor-reported figures as attributed claims, not verified facts. That distinction matters more than usual in this matchup, because the two models have very different amounts of independent data available.
| Benchmark | GPT-5.6 Luna | DeepSeek V4 | Like-for-like? |
|---|---|---|---|
| AA Intelligence Index (Artificial Analysis v4.1) | 51 | 44 (V4-Pro, max reasoning) | Yes — same independent evaluator |
| AA Coding Agent Index v1.3 (Artificial Analysis, read August 2, 2026) | 51.42 (Codex harness, high effort); 58.66 at max | 31.44 (Claude Code harness, high effort) | Same index and same effort, different harnesses |
| SWE-bench Verified (independent) | Not yet charted (too new) | 80.6 percent (DeepSeek self-reports) | No independent head-to-head |
| Context window | 1,050,000 tokens | 1,000,000 tokens | Effectively tied, slight edge Luna |
| Max output tokens | 128,000 tokens | 384,000 tokens | DeepSeek wins on generation length |
The cleanest signal is the Artificial Analysis Intelligence Index, because it is one evaluator running the same battery on both: GPT-5.6 Luna at 51 versus V4-Pro at 44, a clear 7-point lead. The second independent signal runs the same way — the AA Coding Agent Index v1.3 charts GPT-5.6 Luna at 51.42 through the Codex harness at high reasoning effort against 31.44 for DeepSeek V4 Pro through the Claude Code harness at the same effort. So Luna's capability case rests on two independent measurements rather than one, and both point in the same direction. Note also where Luna sits inside its own generation: at max effort it reaches 58.66 on that board against 62.28 for Terra and 66.57 for Sol, all through the same Codex harness — Luna is the economy tier, so it trails its own siblings before it ever meets DeepSeek.
Where we will not overreach is SWE-bench Verified. Luna is too new to be charted on the independent SWE-bench Verified leaderboard as of mid-July 2026, and DeepSeek's widely quoted 80.6 percent is a self-reported figure run on DeepSeek's own harness, not an independently verified result. So there is no clean independent head-to-head on that specific benchmark, and we do not manufacture one. It would be tempting to set DeepSeek's charted score on the AA Coding Agent Index v1.3 beside its own self-reported SWE-bench Verified figure and declare a coding winner, but those are two different benchmarks measured by two different parties — one independent, one self-reported — and comparing them directly would be dishonest. The numbers we can trust — the two Artificial Analysis indices — say clearly that GPT-5.6 Luna is the stronger model on measured capability, and that DeepSeek V4 is far closer on quality than its price would suggest.
Architecture and What Is Actually Different
It is tempting to treat two frontier models as interchangeable black boxes that you poke through an API, but the engineering underneath shapes how they behave, what they cost to run, and where they can be deployed. The two could hardly be more different in philosophy.
GPT-5.6 Luna is a closed model, so OpenAI discloses behavior rather than internals. What it surfaces is a product-level capability set built for high-volume work: the full tool stack on by default, a reasoning-effort scale that runs low, medium, high, and xhigh plus a new max level, and snapshot pinning that gives production teams reproducibility. Prompt caching reads at a 90 percent discount, and the model is tuned to be token-efficient, biasing toward shorter responses that soften the per-task impact of the rate card — which matters more at the volumes Luna is designed for. The trade-offs are real and worth naming: there is no fine-tuning of the Luna base model, it is text and image in but text only out, and it cannot be moved off OpenAI's infrastructure at all. Because Luna is the economy tier, the very hardest reasoning problems are better served by the Terra or Sol tiers above it rather than by pushing Luna past its band.
DeepSeek V4 is the opposite — transparent at the architecture level because the weights and a technical report ship publicly. It is a mixture-of-experts model: V4-Pro carries 1.6 trillion total parameters with about 49 billion active per token, V4-Flash carries 284 billion total with about 13 billion active. The headline innovation is a Hybrid Attention design that combines Compressed Sparse Attention, at four-times compression, with Heavily Compressed Attention, at 128-times compression, to make a 1,000,000-token context affordable to serve. DeepSeek reports this cuts inference compute to a small fraction of the previous generation and shrinks the KV cache dramatically. It bakes three reasoning modes directly into the model rather than bolting them on as a separate API, and it is the first major Chinese frontier model with day-one inference on Huawei Ascend hardware, removing the hard dependency on a single chip vendor. This is why DeepSeek V4 can be both frontier-adjacent in quality and far cheaper on output: the efficiency is engineered in, not just priced in.
The practical upshot is that GPT-5.6 Luna gives you a polished, deeply integrated, multimodal-input agent you cannot inspect or move, while DeepSeek V4 gives you an inspectable, movable, text-only model that you operate yourself. Neither philosophy is wrong; they serve different risk, cost, and sovereignty profiles — and with Luna priced as OpenAI's floor, the cost axis is closer to level than it has ever been between the two houses.
Total Cost of Ownership
Per-token price is the headline, but the real economics depend on volume, caching, and whether you self-host. Here is how to think about it without overstating the case in either direction.
For the hosted-API path, the gap is now small enough that it rarely changes what is buildable. A pipeline that processes, say, a billion output tokens a month costs about 1,200 dollars on GPT-5.6 Luna at standard pricing, around 600 dollars with the Batch API discount, roughly 870 dollars on DeepSeek V4-Pro, and about 280 dollars on V4-Flash. At Luna's Batch rate that is cheaper than V4-Pro outright, and at standard pricing the ratio is about 1.4 to one rather than the tens-to-one you see against Sol — a premium many teams will pay without a second thought for managed infrastructure, image input, and a higher measured score. Prompt caching narrows the input side further: Luna cache reads at 0.02 dollars per million tokens are cheap, and DeepSeek's V4-Pro cache hits now sit just above them at 0.022 dollars off-peak, so stable-prompt workloads with heavy cache reuse no longer favor DeepSeek on that line unless you use V4-Flash.
For the self-hosted path, the calculus flips from per-token billing to capital and operations. DeepSeek's open weights remove the API meter entirely, but you pay in hardware: full-precision V4-Pro requires enterprise GPU clusters, and even V4-Flash needs INT4 or INT8 quantization to fit a single high-end consumer card. For a team with steady, predictable, very high volume and the operational maturity to run model infrastructure, self-hosting V4 can be the cheapest option of all, and the only one that guarantees data never leaves your premises. For a team with spiky or modest volume, the hosted DeepSeek API is the sensible comparison — and it is still cheaper than Luna on output, though no longer on input. The honest conclusion has flipped on one axis: DeepSeek still wins on standard output pricing and on cache hits, but Luna now wins on input and, at Batch rates, on output too — so with Luna you get the measured capability lead, image input, managed operations, and the compliance story without paying more for tokens.
How We Tested
Honesty about methodology matters more in a cross-lab, cross-country comparison than almost anywhere else. Here is exactly what is hands-on and what is research.
We ran both models through their hosted APIs on coding and reasoning prompts to confirm they behave as documented — Luna's tool stack, its reasoning-effort scale including the new max level, and its snapshot pinning, and DeepSeek V4's three thinking modes and OpenAI-compatible endpoint. Those behavioral observations are first-hand. What we have not done is stand up a self-hosted V4-Pro cluster, or run weeks of controlled, identical-task benchmarking of both models against each other on a private suite. For that reason, every capability claim that rests on a number is attributed to its source — Artificial Analysis for the independent Intelligence and Coding Agent indices, and OpenAI or DeepSeek for their own self-reported figures, each labeled as such. We pulled all pricing by fetching each vendor's pricing page directly rather than trusting secondhand summaries. Where we could not verify a like-for-like number — most importantly on SWE-bench Verified, where Luna is not yet charted and DeepSeek's figure is self-reported — we said so and left the head-to-head uncommitted. That is the standard we hold ourselves to, and it is the only honest way to compare a closed US model against an open Chinese one.
Winner by Category
A single overall winner would be dishonest here, because these models are tuned for different buyers. Here is who wins what.
- Best for measured intelligence: GPT-5.6 Luna. It sits at 51 on the Artificial Analysis Intelligence Index, a clear 7 points ahead of V4-Pro at 44.
- Best for measured coding: GPT-5.6 Luna — 51.42 on the AA Coding Agent Index v1.3 through the Codex harness at high effort, against 31.44 for DeepSeek V4 Pro through the Claude Code harness at the same effort. Luna also ships the full agentic tool stack — function calling, web search, code interpreter, computer use, and MCP — on by default.
- Best for cost: split. DeepSeek V4 is about 1.4 times cheaper per output token on V4-Pro and about 4.3 times cheaper on V4-Flash, with cache-hit input pricing that is close to free; GPT-5.6 Luna is about 2.2 times cheaper on input.
- Best for narrowest price gap to a managed flagship: this is the point — with Luna's Batch API the gap does not just narrow, it inverts: Luna bills about 4.4 times less than V4-Pro on input and about 1.45 times less on output, which is what makes the managed option so defensible here.
- Best for open weights and self-hosting: DeepSeek V4. MIT-licensed downloadable weights, with native Huawei Ascend support; Luna cannot be self-hosted at all.
- Best for Western data residency and compliance: GPT-5.6 Luna. US-hosted with regional residency endpoints; DeepSeek's hosted API runs in China, and self-hosting is the only compliant path to the open weights for many buyers.
- Best for long-context work: Near-tie, edge to Luna on raw size (1,050,000 versus 1,000,000 tokens), though DeepSeek allows up to 384K output tokens against Luna's 128K, so heavy generation jobs can favor DeepSeek.
- Best for multimodal input: GPT-5.6 Luna. It accepts image input alongside text; DeepSeek V4 is text only, so any image-in-the-loop workflow needs a separate vision model.
Pros and Cons
GPT-5.6 Luna — Pros
- Leads the Artificial Analysis Intelligence Index at 51, a clear 7 points ahead of DeepSeek V4-Pro at 44.
- OpenAI's cheapest flagship tier: at 0.20 dollars input and 1.20 dollars output per million tokens, it undercuts DeepSeek V4-Pro on input and, at Batch pricing, on output as well.
- Complete agentic tool stack on by default — function calling, structured outputs, web search, file search, code interpreter, hosted shell, computer use, and MCP.
- US-hosted with regional data-residency endpoints, clearing Western compliance bars that DeepSeek's China-hosted API cannot.
- Accepts image input alongside text, and offers prompt caching at a 90 percent discount (0.02 dollars per million cached input tokens) plus a Batch API at half price that drops output to 0.60 dollars.
GPT-5.6 Luna — Cons
- Still costs more per output token than DeepSeek's hosted API at standard rates — 1.20 dollars output per million versus 0.66 dollars off-peak on V4-Flash, though V4-Pro now costs more than Luna at 1.98 dollars.
- Closed model: no self-hosting, no downloadable weights, no data-sovereignty option.
- No fine-tuning of the Luna base model, so tuned production variants must stay on other models.
- Text and image in, but text only out — no native audio or image generation without calling separate tools.
- Not yet charted on the independent SWE-bench Verified leaderboard, so on that particular suite its coding case rests on OpenAI's own reports.
- As the economy tier, it trails its own siblings on the Artificial Analysis Intelligence Index — 51 against Terra's 55 and Sol's 59 — so the hardest problems point up the lineup rather than out to DeepSeek.
DeepSeek V4 — Pros
- Frontier-adjacent capability at open weights: 44 on the Artificial Analysis Intelligence Index, remarkable for a downloadable MIT-licensed model.
- Cheaper hosted API on output at the Flash tier — V4-Flash output at 0.66 dollars per million tokens off-peak is about 1.8 times cheaper than Luna, though V4-Pro at 1.98 dollars is now the more expensive of the two.
- MIT-licensed weights downloadable from Hugging Face for free commercial use, redistribution, and modification.
- Self-hostable for full data sovereignty, with day-one support on Huawei Ascend chips that removes NVIDIA dependency.
- 1,000,000-token context with up to 384K output tokens — larger max output than Luna — plus three built-in reasoning modes to tune cost against quality.
- Low cache-hit input pricing at 0.022 dollars per million tokens off-peak for V4-Pro, which keeps stable-prompt RAG and tool loops cheap, though Luna cache reads at 0.02 dollars now edge it out.
DeepSeek V4 — Cons
- Trails Luna on the independent Intelligence Index, 44 versus 51, and on the AA Coding Agent Index v1.3, 31.44 against 51.42 at the same high effort.
- Hosted API runs in China, a non-starter for US Federal, EU healthcare, and many regulated buyers without self-hosting or a Western reseller.
- Text only — no native image input, so visual workflows need a separate vision model, where Luna reads images directly.
- Open weights, not open source: the training code and data recipe are not released, so the run cannot be fully reproduced.
- Self-hosting requires serious hardware — full-precision V4-Pro needs enterprise GPU clusters, and V4-Flash needs quantization to fit a single high-end card.
- Its price edge over Luna now applies only to standard output and cache hits — Luna is cheaper on input, and cheaper on both lines at Batch rates — so cost alone is a much weaker argument here than against Sol or Terra.
When to Pick Each
When to pick GPT-5.6 Luna
Pick GPT-5.6 Luna when you want a managed frontier model and the price premium over open weights has all but disappeared. If you are running very high-volume, cost-sensitive workloads — bulk classification, extraction, routing, retrieval, cheap agent loops — Luna is the stronger model on the independent Intelligence Index, its tool stack and image input add leverage DeepSeek does not match out of the box, and at Batch pricing it undercuts DeepSeek V4-Pro on both input and output. Pick it if you are a Western enterprise with data-residency or compliance obligations, because US hosting and regional residency endpoints clear bars DeepSeek's China-hosted API cannot. And pick it if you value not operating model infrastructure at all: Luna is a fully managed endpoint, where self-hosting DeepSeek means owning GPUs, quantization, and uptime. If you live inside ChatGPT, Codex, or the Responses API and want the cheapest tier that still reasons, Luna is the natural default. If your tasks are harder than the economy tier is built for, look up the lineup to GPT-5.6 Terra or GPT-5.6 Sol instead, and for where each of those lands against DeepSeek see our roundup of the best AI coding tools of 2026.
When to pick DeepSeek V4
Pick DeepSeek V4 when cost, control, or sovereignty dominate. If you are running very high-volume generation where output token spend is the binding constraint, V4-Pro's output rate — and V4-Flash's, cheaper still — remains below Luna's standard rate, though Luna's Batch tier closes and reverses that gap. Pick it if you need to own your weights: the MIT license lets you self-host, fine-tune, and redistribute, and the Huawei Ascend support means you are not locked to a single chip vendor. Pick it if you are operating where Chinese hosting is acceptable, or where self-hosting is mandatory for data sovereignty, or where you simply need the largest possible output generation at 384K tokens. You give up a measurable slice of frontier capability, image input, and the Western compliance story, but you get most of the quality at a fraction of the price — and you keep total control of where your data lives.
Final Verdict
This is a split verdict by use case — tilted toward GPT-5.6 Luna on capability and toward DeepSeek V4 on cost and openness — and it is the closest the price question gets in this series. Two independent signals score both, and Luna leads on each — the Artificial Analysis Intelligence Index at 51 to 44, and the AA Coding Agent Index v1.3 at 51.42 through Codex against 31.44 for DeepSeek V4 Pro through Claude Code, both at high effort. It is the stronger model on measured capability, the only one that reads images, and the only one that clears Western data-residency requirements. DeepSeek V4, in return, costs about 1.4 times less per output token on V4-Pro and about 4.3 times less on V4-Flash, ships MIT-licensed open weights you can self-host anywhere, matches Luna on context, and beats it on maximum output length — a genuinely remarkable package for an open model.
We did not crown a single overall winner because the two models are not competing for exactly the same buyer. What makes this pairing distinct from Luna's pricier sibling tiers is how defensible the managed choice becomes: because Luna is OpenAI's floor, its Batch API rates now undercut DeepSeek V4-Pro on both input and output rather than trailing by the tens-to-one gap you get with Sol, so choosing more measured intelligence, image input, and US-hosted compliance no longer costs a premium at all. If you need more measured capability, image input, or Western compliance, the answer is GPT-5.6 Luna. If you want to own your weights, need to self-host for sovereignty, or run output-dominated volume at standard rates, the answer is DeepSeek V4. Both answers are correct — for different people. Every benchmark number here is either drawn from the Artificial Analysis independent indices or explicitly attributed to a vendor's own report; only the pricing is fetch-verified directly from each vendor.
If you are weighing DeepSeek V4 against other models, we also ran it head-to-head with OpenAI's top tier in GPT-5.6 Sol vs DeepSeek V4, with the previous OpenAI flagship in GPT-5.5 vs DeepSeek V4, against Anthropic's mid-tier flagship in Claude Sonnet 5 vs DeepSeek V4, against the leading open-weight coding model in GLM-5.2 vs DeepSeek V4, and against the newest open-weight agentic model in Kimi K2.7 Code vs DeepSeek V4. For the deep dive on each model on its own, see our full GPT-5.6 Luna review and DeepSeek V4 review.
Frequently Asked Questions
Is GPT-5.6 Luna better than DeepSeek V4?
On measured capability, yes, and on both independent boards. GPT-5.6 Luna leads the Artificial Analysis Intelligence Index at 51 versus 44 for DeepSeek V4-Pro, and the AA Coding Agent Index v1.3 at 51.42 through the Codex harness against 31.44 for DeepSeek V4 Pro through the Claude Code harness, both at high effort. But DeepSeek V4 is about 1.4 times cheaper per output token on V4-Pro and is open-weight and self-hostable, while Luna is now about 2.2 times cheaper on input, so the better choice depends on whether you are optimizing for capability and compliance or for openness and control.
How much cheaper is DeepSeek V4 than GPT-5.6 Luna?
It depends on the line, and the answer changed twice: on July 30, 2026 when Luna was cut, and on August 16, 2026 when DeepSeek raised every rate. On output tokens, DeepSeek V4-Flash at 0.66 dollars per million off-peak (1.32 at peak) is about 1.8 times cheaper than GPT-5.6 Luna at 1.20 dollars, but V4-Pro at 1.98 dollars off-peak (3.96 at peak) is now about 1.65 times more expensive than Luna, reversing the previous order. On input tokens Luna is the cheaper model against both DeepSeek tiers: at 0.20 dollars it is about 3.3 times cheaper than V4-Pro at 0.66 dollars off-peak, and it now also undercuts V4-Flash at 0.22 dollars, which it did not before. With Luna's Batch API at 0.10 dollars input and 0.60 dollars output, Luna is cheaper than V4-Pro by a wider margin than ever. All prices were fetched directly from each vendor's pricing page in July 2026.
Why is GPT-5.6 Luna cheaper than GPT-5.6 Terra and Sol?
Sol, Terra, and Luna are durable capability tiers in the GPT-5.6 generation rather than different sizes of the same model. Sol is the top tier for the hardest problems at 4 dollars input and 20 dollars output per million tokens. Terra is the balanced, high-volume tier at 2 dollars input and 12 dollars output. Luna is the economy tier at 0.20 dollars input and 1.20 dollars output, built for the highest-throughput, most cost-sensitive work. Luna scores 51 on the Artificial Analysis Intelligence Index against Terra's 55 and Sol's 59 — a small step down at each tier for a large drop in price.
Is DeepSeek V4 open source?
It is open weights, not fully open source. DeepSeek V4 ships its model weights under an MIT license on Hugging Face, allowing free commercial use, redistribution, and modification. However, the training code and data recipe are not released, so the community cannot fully reproduce the training run. You can self-host and fine-tune the model, but you cannot rebuild it from scratch. GPT-5.6 Luna, by contrast, is fully closed and cannot be self-hosted at all.
Can I self-host DeepSeek V4 or GPT-5.6 Luna?
You can self-host DeepSeek V4 because its weights are MIT-licensed and downloadable, including native support for Huawei Ascend chips. You cannot self-host GPT-5.6 Luna — it is a closed model available only through OpenAI's API, ChatGPT, and Codex. Self-hosting V4 requires serious hardware: full-precision V4-Pro needs enterprise GPU clusters, and V4-Flash needs quantization to fit a single high-end consumer card.
What is the context window for each model?
GPT-5.6 Luna ships a 1,050,000-token context window with up to 128K output tokens. DeepSeek V4 provides 1,000,000 tokens of context on both V4-Pro and V4-Flash, with up to 384K tokens of output. The two are effectively tied on raw context length, with Luna slightly larger on input and DeepSeek larger on maximum output — so heavy generation jobs can actually favor DeepSeek.
Which model is better for coding?
Both models carry an independent coding score, and Luna's is the higher one: on the Artificial Analysis Coding Agent Index v1.3, GPT-5.6 Luna is charted at 51.42 through the Codex harness at high reasoning effort against 31.44 for DeepSeek V4 Pro through the Claude Code harness at the same effort. Luna also ships a full agentic tool stack on by default, which helps on real repository-level tasks and multi-step refactors. Separately, DeepSeek self-reports 80.6 percent on SWE-bench Verified, but that is a vendor figure on its own harness, not an independently charted result, so we do not treat it as a head-to-head against Luna's independent score. DeepSeek V4 is still strong and cheaper on standard output, which makes it attractive for high-volume coding where price per token outweighs a 20-point gap on that index.
Is DeepSeek V4 safe to use for a Western company?
It depends on your data-residency rules. DeepSeek's hosted API runs in China, which keeps many regulated buyers — US Federal, EU healthcare — from adopting it without a Western reseller. The MIT-licensed open weights let you sidestep this by self-hosting the model on your own infrastructure anywhere in the world. If compliance is the concern and you cannot self-host, GPT-5.6 Luna's US hosting and regional residency endpoints are the safer default.
How do the two models score on independent benchmarks?
The cleanest independent signals come from Artificial Analysis, which scores both with the same battery. On the Intelligence Index, GPT-5.6 Luna sits at 51 while DeepSeek V4-Pro in maximum reasoning mode scores 44. On the AA Coding Agent Index v1.3, GPT-5.6 Luna is charted at 51.42 through the Codex harness and DeepSeek V4 Pro at 31.44 through the Claude Code harness, both at high effort. Luna is not yet charted on the independent SWE-bench Verified leaderboard, and DeepSeek's 80.6 percent on that benchmark is self-reported, so we do not present a SWE-bench head-to-head.
What are the different DeepSeek V4 tiers?
DeepSeek V4 ships in two sizes. V4-Pro is a 1.6-trillion-parameter mixture-of-experts model with about 49 billion parameters active per token, priced at 0.66 dollars input and 1.98 dollars output per million tokens off-peak (1.32 and 3.96 at peak). V4-Flash is a 284-billion-parameter model with about 13 billion active, priced at 0.22 dollars input and 0.66 dollars output off-peak (0.44 and 1.32 at peak). Both carry a 1,000,000-token context window with up to 384K output, and both support three reasoning modes — Non-Think, Think High, and Think Max.
Does GPT-5.6 Luna have a cheaper mode?
Yes, two cost levers. The Batch API offers a 50 percent discount for asynchronous workloads, bringing GPT-5.6 Luna to 0.10 dollars input and 0.60 dollars output per million tokens. Prompt caching drops repeated input to 0.02 dollars per million tokens on cache reads. With the Batch discount applied, Luna undercuts DeepSeek V4-Pro on both lines — about 4.4 times cheaper on input and about 1.45 times cheaper on output. Luna is already the budget option in the GPT-5.6 lineup, so there is no cheaper OpenAI tier below it.
When were these models released and is this comparison current?
GPT-5.6 Luna became generally available July 9, 2026, across ChatGPT, Codex, and the API. DeepSeek V4 shipped April 24, 2026. This comparison was last updated in July 2026, with all pricing fetched directly from each vendor's pricing page at that time and all benchmark figures either drawn from the Artificial Analysis independent indices or attributed to each vendor's own reports.
Sources and references
Every figure on this page is attributed to whoever produced it. Vendor documentation and independent measurement are listed separately and never merged into a single ranking.
- DeepSeek — API pricing (per-token rates for V4 Pro and V4 Flash)
- Artificial Analysis — DeepSeek V4 Pro (independent index score and cost to run the suite)
- OpenAI — API pricing (per-token, cached and batch rates)
- Artificial Analysis — GPT-5.6 Luna (independent index score)
- Artificial Analysis — Model leaderboard (Intelligence Index scores and cost per task across configurations)
Our Verdict
Split decision, and the narrowest price gap in this series. GPT-5.6 Luna wins measured intelligence on the one independent index that scores both — 51 to 44 on the Artificial Analysis Intelligence Index version 4.1 — though on the AA Coding Agent Index v1.3 it is DeepSeek V4 Pro that carries the only charted score, at 31.44, with Luna absent. It also reads image input, edges the context window at 1,050,000 tokens, and clears Western data-residency requirements. DeepSeek V4 wins on openness and still leads on standard output pricing: about 1.4 times cheaper per output token on V4-Pro, MIT-licensed open weights you can self-host including on Huawei Ascend, near-free cache hits, and a larger 384K maximum output. But OpenAI's July 30, 2026 price cut reshaped the cost axis: at 0.20 dollars per million input tokens, GPT-5.6 Luna is now roughly 2.2 times cheaper than V4-Pro on input, and with the Batch API it undercuts V4-Pro on output as well. Pick GPT-5.6 Luna for more measured intelligence, a charted coding score, image input, managed infrastructure, cheaper input, and US-hosted compliance; pick DeepSeek V4 for open weights, self-hosting sovereignty, near-free cache hits, and the lowest standard output rate.
Choose GPT-5.6 Luna
OpenAI's fastest, most economical GPT-5.6 tier — $0.20 per million input tokens, sub-second warm latency, and a 1.05M-token context for high-volume routine work.
Try GPT-5.6 Luna →Choose DeepSeek V4
Chinese open-source flagship: 1.6T MoE (49B active), 1M context, 80.6% SWE-bench Verified, MIT license — V4-Pro input costs about one-eleventh of Claude Opus 4.7
Try DeepSeek V4 →Frequently Asked Questions
Is GPT-5.6 Luna better than DeepSeek V4?
Split decision, and the narrowest price gap in this series. GPT-5.6 Luna wins measured intelligence on the one independent index that scores both — 51 to 44 on the Artificial Analysis Intelligence Index version 4.1 — though on the AA Coding Agent Index v1.3 it is DeepSeek V4 Pro that carries the only charted score, at 31.44, with Luna absent. It also reads image input, edges the context window at 1,050,000 tokens, and clears Western data-residency requirements. DeepSeek V4 wins on openness and still leads on standard output pricing: about 1.4 times cheaper per output token on V4-Pro, MIT-licensed open weights you can self-host including on Huawei Ascend, near-free cache hits, and a larger 384K maximum output. But OpenAI's July 30, 2026 price cut reshaped the cost axis: at 0.20 dollars per million input tokens, GPT-5.6 Luna is now roughly 2.2 times cheaper than V4-Pro on input, and with the Batch API it undercuts V4-Pro on output as well. Pick GPT-5.6 Luna for more measured intelligence, a charted coding score, image input, managed infrastructure, cheaper input, and US-hosted compliance; pick DeepSeek V4 for open weights, self-hosting sovereignty, near-free cache hits, and the lowest standard output rate.
Which is cheaper, GPT-5.6 Luna or DeepSeek V4?
GPT-5.6 Luna starts at $0.2 in / $1.2 out per M tokens. DeepSeek V4 starts at $0.22 in / $0.66 out per M tokens (free plan available). Check the pricing comparison section above for a full breakdown.
What are the main differences between GPT-5.6 Luna and DeepSeek V4?
The key differences span across 12 features we compared. For AA Intelligence Index (Artificial Analysis v4.1, same evaluator), GPT-5.6 Luna offers 51 while DeepSeek V4 offers 44 (V4-Pro, max reasoning). For AA Coding Agent Index v1.3 (Artificial Analysis, read August 2, 2026), GPT-5.6 Luna offers 51.42 (Codex harness, high effort); 58.66 at max while DeepSeek V4 offers 31.44 (Claude Code harness, high effort). For Input price (per million tokens), GPT-5.6 Luna offers 0.20 dollars while DeepSeek V4 offers Off-peak V4-Pro 0.66, V4-Flash 0.22 dollars (1.32 / 0.44 at peak). See the full feature comparison table above for all details.