Grok 4.5 vs Gemini 3.1 Pro: Aggressive Price vs Multimodal Flagship (2026)
We ran SpaceXAI's Grok 4.5 and Google's Gemini 3.1 Pro side by side. Grok wins cheaper output and coding value; Gemini wins multimodal, context, and EU access.
Feature Comparison
| Feature | Grok 4.5 | Gemini 3.1 Pro Preview |
|---|---|---|
| API input price (per million tokens) | $2.00 up to 200K, $4.00 above 200K (verified) | $2.00 up to 200K, $4.00 above 200K (verified) |
| API output price (per million tokens) | $6.00 up to 200K, $12.00 above 200K (verified) | $12.00 up to 200K, $18.00 above 200K (verified) |
| Cached input price (per million tokens) | $0.30 up to 200K, $0.60 above 200K (verified) | $0.20 up to 200K, $0.40 above 200K (verified) |
| Pricing structure | Context-length tiered above 200K tokens | Context-length tiered above 200K tokens |
| AA Coding Agent Index v1.3 (independent, read Aug 2, 2026) | 64.4 — via Grok Build at high effort | 30.3 — via Gemini CLI at high effort |
| AA Intelligence Index (independent) | 54 | 57 |
| Mean cost per task (independent AA, Coding Agent Index v1.3) | $2.59 | $2.00 |
| LMArena Elo (independent, human preference) | Not charted | 1485 |
| SWE-bench Verified (independent vals.ai) | Not yet on independent leaderboard (too new) | 80.6% self-reported (DeepMind card), not on vals.ai |
| Factual reliability (independent AA-Omniscience) | Index 26, hallucination rate 54% (a flagged weakness) | Not charted on AA-Omniscience |
| Input modalities | Text and image in, text out | Text, image, video, audio, PDF in, text out |
| Declared context window | 500,000 tokens | 1,000,000 tokens |
| Regional availability | Not available in the EU (AI Act systemic-risk designation) | Available in the EU and globally |
| Release status | Generally available (July 9, 2026) | Preview label (deployed since February 2026) |
| Reasoning control | Low, medium, high (high default) | Adaptive thinking with an effort dial (defaults high) |
| Native grounding and search | Function calling and structured outputs; web search as a callable tool | Native Google Search and Maps grounding (5,000 free per month, then $14 per 1,000 queries) |
| Ecosystem and distribution | xAI API, Grok app, X platform | AI Studio, Vertex AI, Gemini CLI, Android Studio, Antigravity |
| Vendor speed claim (unverified) | "Opus-class, much faster" (Elon Musk) — not independently benchmarked | No comparable public speed claim |
Pricing Comparison
Grok 4.5
Gemini 3.1 Pro Preview
Detailed Comparison
Grok 4.5 and Gemini 3.1 Pro are the two models compared here. Grok 4.5 is SpaceXAI's flagship reasoning model, generally available July 9, 2026, priced at $2.00 per million input tokens and $6.00 per million output tokens for prompts up to 200,000 tokens, with a 500,000-token context window, text-and-image input, and availability in the European Union. Gemini 3.1 Pro is Google DeepMind's flagship, priced at $2 per million input tokens and $12 per million output for prompts up to 200,000 tokens, with a 1,000,000-token context window and native text, image, video, audio, and PDF input, available in the EU. This is a split verdict. Grok 4.5 leads on cheaper output and the independent Coding Agent Index v1.3 (64.4 through Grok Build against 30.3 for Gemini CLI). Gemini 3.1 Pro leads on native multimodal input, a higher Artificial Analysis Intelligence Index (57 to 54), a charted LMArena Elo of 1485, and double the context. Best for cheap output and coding value: Grok 4.5. Best for native multimodal input and intelligence: Gemini 3.1 Pro.
Quick Verdict
This is a split verdict between SpaceXAI's aggressively priced flagship and Google's multimodal flagship, and neither wins outright — Grok 4.5 takes output price and coding value, while Gemini 3.1 Pro takes native multimodality, aggregate intelligence, context, and EU availability. Grok 4.5 went generally available on July 9, 2026, three days before this comparison; Gemini 3.1 Pro has been Google's deployed flagship since February 2026 and sits in our production stack through Google AI Studio and Vertex AI. We have API access to both and have run them side by side, so we scope Grok's hands-on claims to roughly 72 hours of first impressions and lean on attributed third-party benchmarks — Artificial Analysis, LMArena, and vals.ai — wherever our own time is too short. Every figure below carries its source, and vendor claims are labeled as such. Here is the short version.
- Best on the independent agentic-coding leaderboard: Grok 4.5. On the Artificial Analysis Coding Agent Index v1.3, Grok Build with Grok 4.5 at high effort scores 64.4 against 30.3 for Gemini CLI with Gemini 3.1 Pro at high effort — a 34-point gap, read August 2, 2026.
- Best on aggregate intelligence: Gemini 3.1 Pro. It scores 57 on the Artificial Analysis Intelligence Index against Grok's 54 — a three-point gap on the same index, with Grok sitting fourth behind the current frontier leaders.
- Best for output price: Grok 4.5, decisively. Its $6 per million output tokens is half of Gemini's $12 up to 200,000 tokens, and above that band Grok's $12 is two-thirds of Gemini's $18. For output-heavy generation, this is the single biggest cost lever on the page.
- Best for cached-read price: Gemini 3.1 Pro. Its $0.20 per million cached input tokens up to 200,000 tokens undercuts Grok's $0.30, and its $0.40 above that band undercuts Grok's $0.60, so cache-heavy workloads that replay large prompts pay less on Gemini.
- Best for native multimodal input: Gemini 3.1 Pro. It accepts native text, image, video, audio, and PDF; Grok 4.5 takes only text and image. For video and audio understanding in a single call, Gemini is the only option of the two.
- Best for long context: Gemini 3.1 Pro. Its 1,000,000-token context window is double Grok's 500,000, so book-length corpora and very large codebases fit in one call on Gemini where they may not on Grok.
- Best for pricing structure: neither. Both tier at the same 200,000-token threshold: input doubles to $4 on each, while above that band Grok’s output doubles to $12 and Gemini’s rises to $18.
- Best for the lowest independent cost per task: Gemini 3.1 Pro. On the same Coding Agent Index v1.3 runs, Artificial Analysis measures a mean $2.00 per task for Gemini CLI with Gemini 3.1 Pro against $2.59 for Grok Build with Grok 4.5 — the one independent cost line where the two are directly comparable.
- Best for human-preference evidence: Gemini 3.1 Pro. It is charted at 1485 on LMArena, where Grok 4.5 is absent — an availability of evidence rather than a proven quality gap.
- EU availability: both, since July 17, 2026, when SpaceXAI opened Grok 4.5 to EU users in the API console. Before that date only Gemini 3.1 Pro was reachable from the EU.
The honest caveats up front: Grok 4.5 has been public for three days, so we treat our hands-on notes as first impressions, not a settled verdict. The two vendors publish different benchmarks, so we compare only where the ground is solid. Neither model has an independently verified SWE-bench Verified score — Grok 4.5 is not yet on the independent vals.ai leaderboard, and Gemini's widely cited 80.6 percent is self-reported on DeepMind's model card, not run by vals.ai. Grok 4.5 is not charted on the LMArena Elo board that ranks Gemini, while both models do appear on the Coding Agent Index. And SpaceXAI's own framing of Grok 4.5 as "Opus-class, much faster" is a vendor claim we label rather than adopt. We flag every one of those gaps rather than fill it.
Grok 4.5 vs Gemini 3.1 Pro — Overview
What Is Grok 4.5?
Grok 4.5 is the flagship reasoning model of SpaceXAI, generally available July 9, 2026 through the xAI API, and the successor to Grok 4.3 as the company's frontier model. We review it in depth in our Grok 4.5 review. Per SpaceXAI's model documentation, Grok 4.5 runs a 500,000-token context window, accepts text and image input to text output, and offers a reasoning-effort scale of low, medium, and high, with high as the default. It supports function calling and structured outputs, publishes rate limits of 150 requests per second and 50 million tokens per minute, and serves from the us-east-1 and us-west-2 regions. API pricing is $2.00 per million input tokens, $0.30 per million cached input tokens, and $6.00 per million output tokens for prompts up to 200,000 tokens, doubling to $4.00, $0.60, and $12.00 above that band — xAI positions this as roughly half the price of rival flagships. Two facts frame the model. First, its founder Elon Musk describes it publicly as "Opus-class, much faster," a vendor claim we label and test against independent numbers rather than take at face value. Second, Grok 4.5 was not available in the European Union for its first nine days, a gap SpaceXAI's rollout closed on July 17, 2026; both models are reachable from the EU today.
What Is Gemini 3.1 Pro?
Gemini 3.1 Pro is Google DeepMind's flagship Gemini 3 series model, announced February 19, 2026 and still carrying the Preview label on its gemini-3.1-pro-preview model ID as of July 2026, even as it powers Google's frontier developer surfaces. We review it in depth in our Gemini 3.1 Pro review (our score: 9.0 out of 10). Per Google's model documentation and DeepMind's model card, it runs a 1,000,000-token input context with up to 64,000 output tokens and a January 2025 knowledge cutoff, and it accepts native multimodal input across text, image, video, audio, and PDF, returning text. It uses adaptive thinking shaped by an effort dial rather than an explicit extended-thinking flag, ships native Google Search and Maps grounding as first-party tools, and offers the widest first-party distribution of any frontier vendor — Google AI Studio, Vertex AI, the Gemini API and app, the Gemini CLI, Android Studio, and Antigravity. API pricing uses context-length tiering, which we verified directly on Google's pricing page: $2 per million input tokens and $12 output for prompts up to 200,000 tokens, rising to $4 and $18 above that. For the faster, cheaper sibling model, see our Gemini 3 Flash review.
How We Compared Them — and What We Did Not Do
Method transparency matters more than usual here, because Grok 4.5 is three days old at the time of writing and the two vendors publish different benchmarks that are easy to conflate. Here is exactly what we did and did not do, so you can weigh every claim below against its source. Our full methodology mirrors what we describe in our agentic coding model explainer.
- Pricing: both rate cards are vendor-verified at the source. Grok 4.5's $2.00 input and $6.00 output per million tokens up to 200,000 prompt tokens, doubling above that band, is confirmed against SpaceXAI's model and pricing documentation; Gemini 3.1 Pro's tiered $2 and $12 (up to 200,000 tokens) is confirmed against Google's pricing page, including the higher $4 and $18 band above 200,000 tokens. No relayed figures.
- Independent benchmarks: we lean on Artificial Analysis (Intelligence Index and AA-Omniscience), its separate Coding Agent Index (v1.3, read August 2, 2026), and LMArena (Elo). We only declare a benchmark winner where both models were measured on the same suite under consistent conditions — and we say plainly when only one of them is charted.
- Data gaps we flag rather than fill: neither model appears on the independent vals.ai SWE-bench Verified board. Grok 4.5 is too new to be listed there; Gemini's 80.6 percent is self-reported on DeepMind's model card. Both models are charted on the Coding Agent Index v1.3 — Grok Build with Grok 4.5 at 64.4, Gemini CLI with Gemini 3.1 Pro at 30.3 — while Grok is not on the LMArena board that lists Gemini at 1485. We do not substitute one model's number for the other's missing one.
- Vendor claims: SpaceXAI's "Opus-class, much faster" framing for Grok 4.5, and DeepMind's GPQA Diamond, ARC-AGI-2, and SWE-bench Verified numbers for Gemini, are labeled as vendor-reported and not treated as head-to-head evidence.
- Hands-on: we have run Gemini 3.1 Pro through Google AI Studio and Vertex AI on our content workflow since April 2026, and Grok 4.5 for roughly 72 hours since its July 9 GA, side by side on the same business tasks. That is enough for first impressions on Grok, not a controlled benchmark, and we scope every observation accordingly.
- Disclosure: we have no affiliate relationship with SpaceXAI or Google. There are no sponsored links on this page. Our team uses Gemini 3.1 Pro in production, which is exactly why we have held this comparison to independent, attributed numbers rather than our own habit.
Features and Benchmarks Comparison
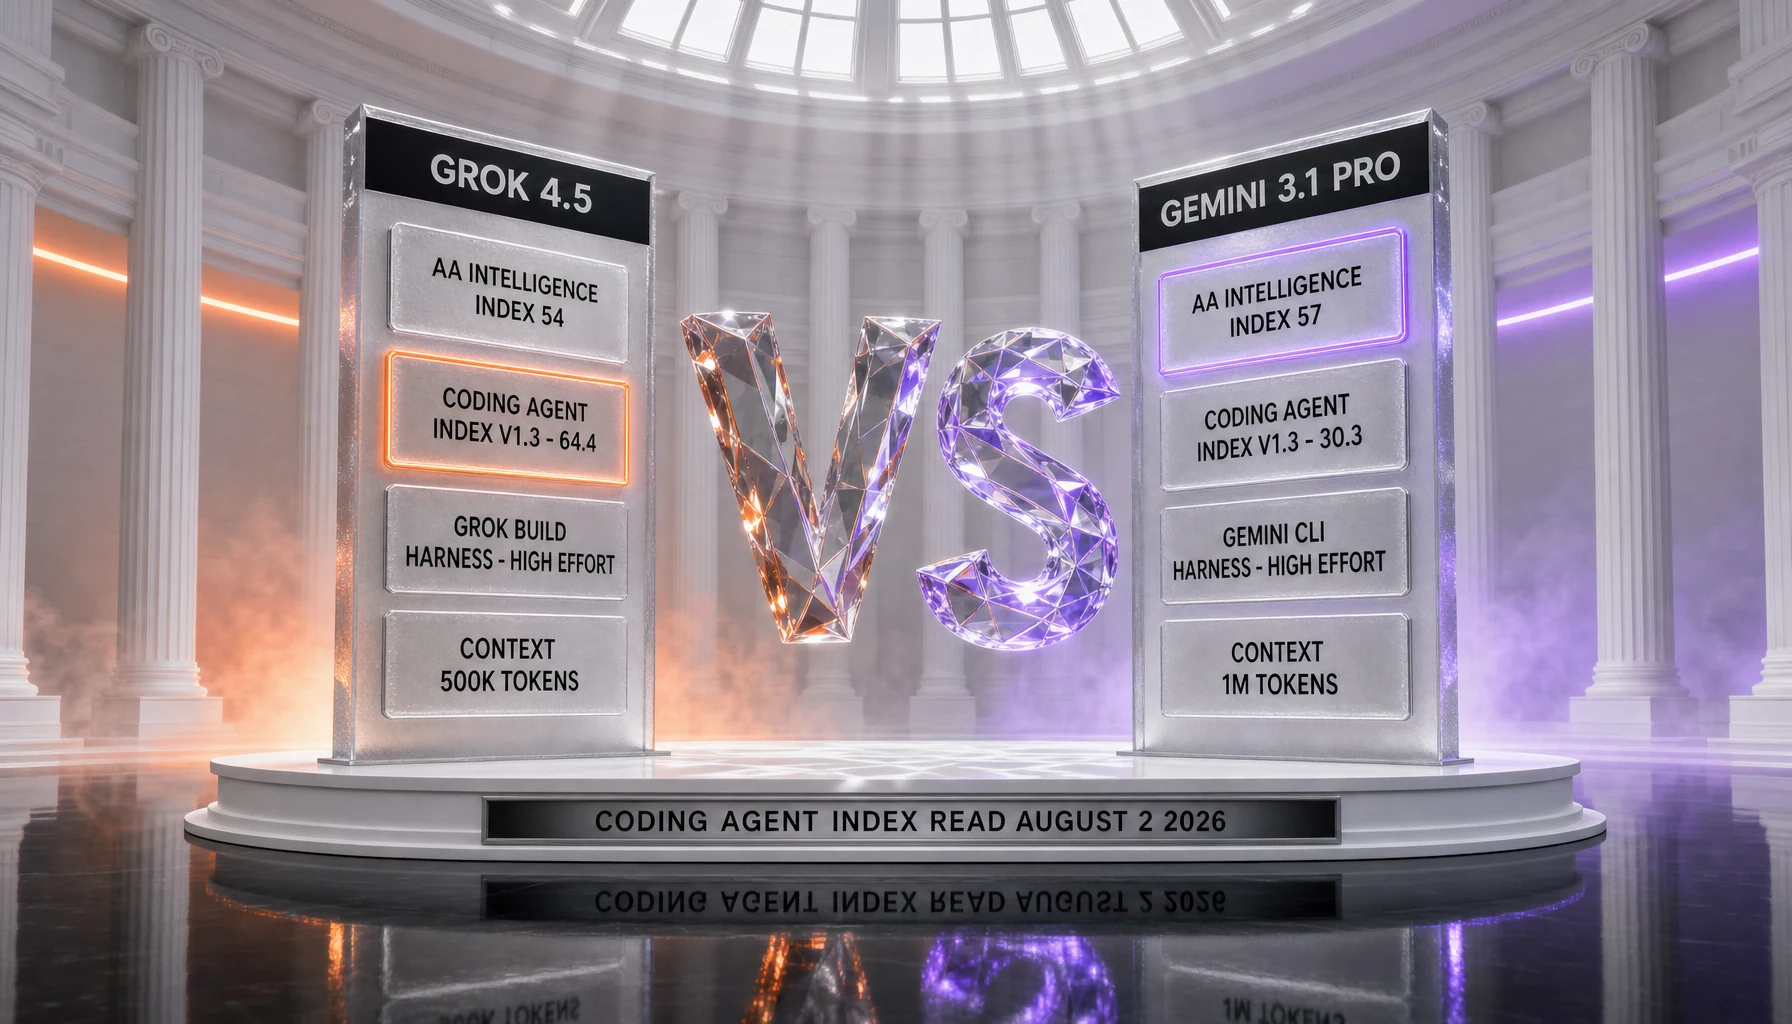
The table below lists every dimension we could verify or attribute. Read the Winner column carefully: it distinguishes vendor-verified pricing, independent benchmarks, and vendor claims, and it marks a tie whenever the two are level or measured on different suites. A dash means the model is not charted on that board, which we treat as a data gap, not a zero.
| Dimension | Grok 4.5 | Gemini 3.1 Pro | Winner |
|---|---|---|---|
| API input price (per million tokens) | $2.00 up to 200K, $4.00 above 200K (verified) | $2.00 up to 200K, $4.00 above 200K (verified) | Tie (identical at both bands) |
| API output price (per million tokens) | $6.00 up to 200K, $12.00 above 200K (verified) | $12.00 up to 200K, $18.00 above 200K (verified) | Grok 4.5 |
| Cached input price (per million tokens) | $0.30 up to 200K, $0.60 above 200K (verified) | $0.20 up to 200K, $0.40 above 200K (verified) | Gemini 3.1 Pro |
| Pricing structure | Context-length tiered above 200K tokens | Context-length tiered above 200K tokens | Tie |
| AA Coding Agent Index v1.3 (independent, read Aug 2, 2026) | 64.4 — via Grok Build at high effort | 30.3 — via Gemini CLI at high effort | Grok 4.5 |
| AA Intelligence Index (independent) | 54 | 57 | Gemini 3.1 Pro |
| Mean cost per task (independent AA, Coding Agent Index v1.3) | $2.59 | $2.00 | Gemini 3.1 Pro |
| LMArena Elo (independent, human preference) | Not charted | 1485 | Gemini 3.1 Pro |
| SWE-bench Verified (independent vals.ai) | Not yet on independent leaderboard (too new) | 80.6% self-reported (DeepMind card), not on vals.ai | Tie (neither independently verified) |
| Factual reliability (independent AA-Omniscience) | Index 26, hallucination rate 54% (a flagged weakness) | Not charted on AA-Omniscience | Tie (only Grok charted) |
| Input modalities | Text and image in, text out | Text, image, video, audio, PDF in, text out | Gemini 3.1 Pro |
| Declared context window | 500,000 tokens | 1,000,000 tokens | Gemini 3.1 Pro |
| Regional availability | Available in the EU since July 17, 2026; served from US regions | Available in the EU and globally | Tie on availability |
| Release status | Generally available (July 9, 2026) | Preview label (deployed since February 2026) | Grok 4.5 |
| Reasoning control | Low, medium, high (high default) | Adaptive thinking with an effort dial (defaults high) | Tie |
| Native grounding and search | Function calling and structured outputs; web search as a callable tool | Native Google Search and Maps grounding (5,000 free per month, then $14 per 1,000 queries) | Gemini 3.1 Pro |
| Ecosystem and distribution | xAI API, Grok app, X platform | AI Studio, Vertex AI, Gemini CLI, Android Studio, Antigravity | Gemini 3.1 Pro |
| Vendor speed claim (unverified) | "Opus-class, much faster" (Elon Musk) — not independently benchmarked | No comparable public speed claim | Tie (vendor claim only) |
Two symmetries stand out. Grok 4.5 leads the independent agentic-coding board by a wide margin (the Coding Agent Index v1.3, at 64.4 through Grok Build against 30.3 for Gemini CLI); Gemini owns the one independent human-preference board that scores it (LMArena at 1485), where Grok is absent, and it completes those same coding tasks more cheaply, at a mean $2.00 per task against $2.59. And on aggregate intelligence the two are three points apart on Artificial Analysis, with Gemini ahead. This is why the verdict splits rather than crowning one model, and why we lean hard on each vendor's own documentation for the specification rows. The one row that rewards a careful read is factual reliability: Artificial Analysis flags Grok 4.5 with a 54 percent hallucination rate on its AA-Omniscience index, and Gemini 3.1 Pro is not charted there, so we present Grok's number as a documented caution rather than award Gemini a win it has no comparable score for.
Pricing Comparison
Pricing is where the two models diverge most cleanly, and both rate cards are vendor-verified. Both models tier their rates by prompt size at the same 200,000-token threshold. We confirmed Grok on SpaceXAI's documentation and Gemini on Google's pricing page. For the plain-English version of what input, output, and cached tokens actually mean, see our AI model pricing explainer.
- Standard input: level at the common band. Both charge $2 per million input tokens for prompts up to 200,000 tokens, and both rise to $4 above that. Input is therefore identical at both bands, and neither model is the cheaper choice on this line at any prompt size.
- Standard output: this is Grok 4.5's decisive win. Its $6 per million output tokens is half of Gemini's $12 up to 200,000 tokens, and above that band Grok's $12 is two-thirds of Gemini's $18. Because output tokens usually dominate the bill on generation-heavy work, this single line is the strongest cost argument on the page — a workload that emits far more than it ingests costs roughly half as much on Grok.
- Cached input: here Gemini 3.1 Pro turns the tables. It charges $0.20 per million cached input tokens up to 200,000 tokens (rising to $0.40 above) against Grok's $0.30, and $0.40 against Grok's $0.60 above that band, so workloads that replay large cached prompts — retrieval-augmented chat, long system prompts — pay less on Gemini. Note that Gemini adds a $4.50 per million tokens per hour cache-storage fee that Grok does not.
- Pricing predictability: neither card spares you the per-request math. A prompt that crosses 200,000 tokens doubles the input rate on both models; above that line Grok’s output doubles while Gemini’s rises by half, so budgeting is a per-request calculation on either one.
- Free access: Gemini offers free interactive testing through Google AI Studio but no free tier on the paid API. Grok 4.5 is an API and Grok-app model, with consumer access through the Grok app and X platform rather than a free developer tier.
The practical read: for output-heavy generation, Grok 4.5 is materially cheaper. For cache-heavy workloads on ordinary prompt sizes, Gemini 3.1 Pro's cheaper cached reads and its identical $2 input make it competitive, and it stays cheaper on output only if you never look at the raw output line. On an independent basis, Artificial Analysis measures the mean cost of the Coding Agent Index v1.3 runs at $2.59 per task for Grok Build with Grok 4.5 and $2.00 for Gemini CLI with Gemini 3.1 Pro, so the like-for-like independent comparison favors Gemini on cost per task even though Grok is far cheaper per token.
Winner by Category
Because the two models are strong on different axes, the useful question is not which is better overall but which wins each job. Here is how the categories fall, with the source for each call.
- Agentic coding (independent): Grok 4.5. On the Artificial Analysis Coding Agent Index v1.3 it scores 64.4 against 30.3 for Gemini 3.1 Pro — the widest independent gap on this page — though Gemini finishes the same tasks for less, at a mean $2.00 against $2.59.
- Output price: Grok 4.5. $6 per million output tokens against Gemini's $12 up to 200,000 tokens is the biggest single cost gap on the page.
- Multimodal input: Gemini 3.1 Pro. Native video, audio, and PDF input in a single call is a capability Grok simply does not have — Grok is text and image in, text out.
- Aggregate intelligence: Gemini 3.1 Pro. 57 to 54 on the Artificial Analysis Intelligence Index, with Grok charted fourth behind the current frontier leaders.
- Context length: Gemini 3.1 Pro. Its 1,000,000-token window is double Grok's 500,000, so the largest corpora and codebases fit in one call where they may not on Grok.
- Human preference: Gemini 3.1 Pro on the record, because it is charted at 1485 on LMArena and Grok is not charted — an availability of evidence rather than a proven quality gap.
- Pricing structure: a tie. Both tier at 200,000 prompt tokens, so neither card is the more predictable one.
- Factual reliability: a caution on Grok. Artificial Analysis's AA-Omniscience index flags a 54 percent hallucination rate for Grok 4.5; Gemini 3.1 Pro has no comparable independent score, so we treat this as a documented reason to verify Grok's factual output, not as a Gemini win.
- Ecosystem depth: Gemini 3.1 Pro. The widest first-party distribution of any frontier vendor, from Vertex AI to Android Studio, plus native Google grounding.
- Regional availability: Gemini 3.1 Pro. It has been available in the European Union throughout, where Grok 4.5 arrived on July 17, 2026.
Pros and Cons
Grok 4.5 Pros and Cons
What we like about Grok 4.5
- Cheapest output of the two. $6 per million output tokens against Gemini's $12 up to 200,000 tokens, and $12 against $18 above that band — the strongest cost lever on generation-heavy work.
- Independent agentic-coding score. 64.4 on the Coding Agent Index v1.3 through Grok Build at high effort, more than double Gemini 3.1 Pro's 30.3 on the same board.
- Generally available. A GA contract as of July 9, 2026, rather than a Preview label, with function calling and structured outputs at launch.
- Aggressive positioning. xAI prices it at roughly half of rival flagships, and its founder frames it as "Opus-class, much faster" — a vendor claim, but a signal of intent on speed and value.
Where Grok 4.5 falls short
- Text and image input only. No native video or audio, where Gemini accepts both — a hard gap for multimodal workloads.
- Half the context window. 500,000 tokens against Gemini's 1,000,000, so the very largest single-call corpora do not fit.
- Flagged hallucination rate. A 54 percent hallucination rate on the independent AA-Omniscience index, a documented reason to verify factual output.
- Not on the LMArena board and no independent SWE-bench score. Too new to be charted on either, so its strongest coding evidence is the Coding Agent Index v1.3 alone.
- Three days old at the time of testing. Public for roughly 72 hours at the time of writing, so its behavior over weeks was unproven; it was also closed to EU users then, until July 17, 2026.
Gemini 3.1 Pro Pros and Cons
What we like about Gemini 3.1 Pro
- Native multimodal input. Text, image, video, audio, and PDF in a single call — the clearest capability Grok cannot match.
- Double the context window. 1,000,000 tokens against Grok's 500,000, for book-length inputs and very large codebases in one call.
- Marginally higher aggregate intelligence. 57 on the Artificial Analysis Intelligence Index against Grok's 54, and charted at 1485 on LMArena.
- Native Google Search and Maps grounding. 5,000 free prompts per month, then $14 per 1,000 queries, for sourced answers without a retrieval pipeline.
- Deepest first-party distribution. AI Studio, Vertex AI, Gemini CLI, Android Studio, and Antigravity.
Where Gemini 3.1 Pro falls short
- Twice the output price on ordinary prompts. $12 per million output tokens up to 200,000 tokens against Grok's $6, and $18 above that band against Grok's $12.
- Cache-storage fee. Gemini bills $4.50 per million tokens per hour to keep a context cache warm, a line Grok’s rate card does not carry.
- Still a Preview model. Google's Preview label carries change-management risk, with a real shutdown precedent from March 2026.
- Older knowledge cutoff. A January 2025 cutoff means it leans on grounding for recent events, where a fresher model would not.
- Well behind on the AA Coding Agent Index. 30.3 through Gemini CLI at high effort on the v1.3 board, against 64.4 for Grok Build with Grok 4.5.
When to Pick Grok 4.5 vs Gemini 3.1 Pro
Pick Grok 4.5 if...
- Your workload is output-heavy and cost-sensitive — $6 per million output tokens is half of Gemini's rate up to 200,000 tokens.
- Your work is agentic coding measured on the AA Coding Agent Index v1.3, where Grok scores 64.4 and Gemini 3.1 Pro trails at 30.3.
- You need a generally available contract rather than a Preview model that can change with limited notice.
- You can add your own fact-checking layer to offset the flagged hallucination rate.
Pick Gemini 3.1 Pro if...
- Your inputs are multimodal — native video, audio, and PDF in a single call, which Grok cannot accept.
- You need the full 1,000,000-token context window for the largest corpora and codebases in one call.
- You want native Google Search and Maps grounding for sourced, up-to-date answers without building retrieval.
- Your stack is Google-native — AI Studio, Vertex AI, the CLI, Android Studio, or Antigravity give the shortest path to production.
- You want the marginally higher aggregate-intelligence score and a charted human-preference Elo.
Frequently Asked Questions
Is Grok 4.5 better than Gemini 3.1 Pro in 2026?
It depends on the job, and we will not fake a single overall winner. Grok 4.5 leads where cost and coding value matter: its $6 per million output tokens is half of Gemini's $12 up to 200,000 tokens, it scores 64.4 on Artificial Analysis's independent Coding Agent Index v1.3 against 30.3 for Gemini 3.1 Pro, though Gemini completes those same tasks for less, at a mean $2.00 per task against $2.59. Gemini 3.1 Pro leads on breadth: native multimodal input across text, image, video, audio, and PDF that Grok cannot match, a marginally higher Artificial Analysis Intelligence Index of 57 against 54, a charted LMArena Elo of 1485, double the context at 1,000,000 tokens, and availability in the European Union where Grok is not offered. Best for cheap output and coding value: Grok 4.5. Best for native multimodal input, intelligence, and context: Gemini 3.1 Pro.
How much do Grok 4.5 and Gemini 3.1 Pro cost?
Grok 4.5 costs $2 per million input tokens, $0.30 per million cached input tokens, and $6 per million output tokens for prompts up to 200,000 tokens, doubling to $4, $0.60, and $12 above that band — we confirmed this on SpaceXAI's model documentation. Gemini 3.1 Pro uses context-length tiering, which we verified on Google's pricing page: for prompts up to 200,000 tokens it costs $2 per million input and $12 per million output; above 200,000 tokens it rises to $4 input and $18 output, with cached input at $0.20 and $0.40 per million respectively plus a $4.50 per million tokens per hour cache-storage fee. Input is level at the standard band ($2 each). On output Grok is decisively cheaper — half or a third of Gemini's rate. On cached reads Gemini is cheaper at $0.20 against Grok's $0.30. Both have been reachable from the EU since July 17, 2026.
Which is better for coding: Grok 4.5 or Gemini 3.1 Pro?
On the one independent board that scores both, Grok 4.5 leads by a wide margin. On the Artificial Analysis Coding Agent Index v1.3, Grok Build with Grok 4.5 at high effort scores 64.4 against 30.3 for Gemini CLI with Gemini 3.1 Pro at high effort. On SWE-bench Verified, the independent vals.ai leaderboard lists neither model directly — Grok 4.5 is too new to appear there, and Gemini's widely cited 80.6 percent comes from DeepMind's own model card, not an independent run. So the honest picture is: Grok has the stronger independent agentic-coding signal and a much cheaper output rate, Gemini has a published SWE-bench Verified number but a self-reported one, and neither has an independently verified SWE-bench Verified score on vals.ai. If you weight independent agentic-coding results and output cost, Grok leads; if you weight vendor model-card SWE-bench numbers, Gemini has one and Grok does not.
Why is Grok 4.5's SWE-bench score not listed here?
Because Grok 4.5 does not have an independently verified SWE-bench Verified score at the time of writing. It is too new to appear on the independent vals.ai leaderboard that runs the benchmark under controlled conditions, and we do not publish an unverified figure in its place. Gemini 3.1 Pro's widely cited 80.6 percent comes from DeepMind's own model card, not vals.ai, so we label it self-reported and never present it as third-party evidence. We keep independent and vendor-reported numbers strictly apart: Grok's verifiable coding evidence is its 64.4 on Artificial Analysis's Coding Agent Index v1.3, where Gemini 3.1 Pro is charted at 30.3, and Gemini's human-preference evidence is its 1485 on LMArena. Anyone who tells you Grok 4.5 has a specific independent SWE-bench Verified percentage is citing a number that is not on the independent board.
Is Grok 4.5 really cheaper than Gemini 3.1 Pro?
On output, yes, decisively — and we verified both rate cards at the source. Grok 4.5's $6 per million output tokens is half of Gemini's $12 up to 200,000 tokens, and above that band Grok's $12 is two-thirds of Gemini's $18. Since output tokens usually dominate the bill on generation-heavy work, a workload that emits far more than it ingests costs roughly half as much on Grok. The picture is more even elsewhere: input is identical at $2 per million on ordinary prompts, and on cached reads Gemini is actually cheaper at $0.20 against Grok's $0.30. So Grok is the cheaper model for output-heavy generation, while Gemini is competitive on cache-heavy, ordinary-sized workloads. For raw output cost, Grok wins clearly; for cache-heavy retrieval workloads, Gemini can come out ahead.
Which has the larger context window: Grok 4.5 or Gemini 3.1 Pro?
Gemini 3.1 Pro, by a factor of two. Google's documentation lists Gemini 3.1 Pro at a 1,000,000-token input context with up to 64,000 output tokens and a January 2025 knowledge cutoff. SpaceXAI's documentation lists Grok 4.5 at a 500,000-token context window with text and image input. Both handle large documents and multi-file codebases, but Gemini's window is twice as large, so the very biggest single-call corpora — an entire large repository, a book plus its references — fit on Gemini where they may need chunking on Grok. If your workload routinely pushes past 500,000 tokens in one call, Gemini is the model of the two that can take it. If your prompts sit comfortably under that ceiling, Grok's 500,000 tokens is ample and comes with a much cheaper output rate.
What can Gemini 3.1 Pro do that Grok 4.5 cannot?
The clearest capability gap is native multimodal input. Gemini 3.1 Pro accepts text, image, video, audio, and PDF in a single call and returns text, which lets you drop a video walkthrough plus a slide deck into one prompt and get structured output. Grok 4.5 accepts only text and image input to text output. Gemini also ships native Google Search and Maps grounding as first-party tools (5,000 prompts per month free across the Gemini 3 family, then $14 per 1,000 queries), and carries a 1,000,000-token context window that is double Grok's, in the European Union where Grok 4.5 is not. It has the deepest first-party distribution of any frontier vendor, spanning Google AI Studio, Vertex AI, the Gemini CLI, Android Studio, and Antigravity. If your workload is multimodal extraction, retrieval-grounded answering, very-long-context work, or anything embedded in the Google Cloud stack, those are real Gemini advantages Grok does not match.
What can Grok 4.5 do that Gemini 3.1 Pro cannot?
Grok 4.5's differentiators are output price, coding value, and GA status. Its $6 per million output tokens is half of Gemini's rate up to 200,000 tokens, so output-heavy generation costs materially less. It carries an independent Artificial Analysis Coding Agent Index v1.3 score of 64.4 against Gemini 3.1 Pro's 30.3 on the same board. Its rate card tiers at 200,000 prompt tokens, the same threshold Gemini uses. And Grok 4.5 is generally available as of July 9, 2026, whereas Gemini 3.1 Pro still carries Google's Preview label. Its founder frames it as "Opus-class, much faster," which we treat as a vendor claim pending independent latency benchmarks. For output-cost-sensitive generation and agentic-coding value, Grok has the edge.
Is Grok 4.5 multimodal?
Partly. Grok 4.5 accepts text and image input and produces text output. It does not support native audio or video input. For document work, its vision input covers scanned pages, charts, and screenshots, which covers many business tasks. If your workload requires native video or audio understanding in a single call, Gemini 3.1 Pro is the model of the two that can do it — it accepts text, image, video, audio, and PDF natively. So Grok is multimodal on input in a limited sense (text and image), while Gemini is fully multimodal on input. This is one of the clearest lines between the two: for anything involving native video or audio, Gemini is the only choice here, and for text-and-image work at a cheaper output rate, Grok is competitive.
Is Grok 4.5 available in the European Union?
Yes, since July 17, 2026. SpaceXAI did not offer Grok 4.5 in the European Union at launch, a gap reported as following from the EU AI Act's systemic-risk designation for the most capable general-purpose models. We present this as a neutral availability fact rather than a judgment on the model or the regulation: the xAI release notes recorded on July 17, 2026 that "Grok 4.5 is now available in the API console for EU users," so both are options inside the EU. Gemini 3.1 Pro — which is available in the EU and globally — is the model of the two you can deploy there. Both models are now reachable through their respective APIs from the EU as well, and this comparison applies in full. For EU-based teams the availability gap was decisive on its own for nine days after launch; it closed on July 17, 2026.
How reliable is Grok 4.5 on factual questions?
Independent data flags factual reliability as a Grok 4.5 weakness. On Artificial Analysis's AA-Omniscience index, Grok 4.5 scores 26 with a 54 percent hallucination rate — meaning it produces confident but incorrect answers on a majority of the index's hardest factual questions. Gemini 3.1 Pro is not charted on AA-Omniscience, so we cannot present a head-to-head number; we report Grok's figure as a documented caution rather than a comparative win for Gemini. The practical implication is that Grok 4.5's much cheaper output rate comes with a stronger case for a verification layer — retrieval grounding, citation checks, or human review — on any factual or high-stakes output. Gemini's answer to the same problem is its native Google Search and Maps grounding, which can supply sourced context at generation time and is one reason it is used in production on our own content workflow.
Can Grok 4.5 and Gemini 3.1 Pro work together in the same stack?
Yes, and a split stack is a rational setup given how differently they are strong. A practical routing pattern sends output-heavy generation and agentic coding measured on the Coding Agent Index to Grok 4.5, where the $6 output rate and the 64.4 coding index result pay off, and sends multimodal work, very-long-context tasks, Google-grounded retrieval, and any EU-based deployment to Gemini 3.1 Pro, where it accepts native video and audio and is legally available. Abstraction layers such as the Vercel AI SDK, LangChain, or LiteLLM turn cost-and-capability routing by task type into a configuration exercise rather than a rewrite. Because the two lead on different axes — Grok on output cost and coding value, Gemini on modality, context, and reach — they are genuinely complementary, and many teams route by workload rather than standardizing on a single model. That routing pattern now applies inside the EU too, where Grok was unavailable until July 17, 2026.
Final Verdict — A Split Between Cheap Output and Multimodal Breadth
After running both side by side, verifying pricing on both vendors' own documentation, and holding every capability claim to independent benchmarks, our verdict is a genuine split. Grok 4.5 is the cheap-output-and-coding-value pick: its $6 per million output tokens is half of Gemini's rate up to 200,000 tokens, it scores 64.4 on the independent Coding Agent Index v1.3 against Gemini's 30.3, and it ships as a generally available model. Gemini 3.1 Pro is the multimodal-breadth-and-reach pick: it accepts native video, audio, and PDF input that Grok cannot, scores marginally higher on aggregate intelligence at 57 to 54, is charted on LMArena at 1485 where Grok is absent, doubles the context window to 1,000,000 tokens, and is available in the European Union where Grok is not. We disclose plainly that our team runs Gemini 3.1 Pro in production — which is exactly why we anchored every capability comparison to third-party numbers rather than our own habit, and why we flag Grok's 54 percent hallucination rate on AA-Omniscience as a documented caution rather than bury it.
We did not crown a single overall winner because the evidence does not support one honestly. Grok wins the cost lines that matter most on generation-heavy work and the one independent coding board that scores it; Gemini wins the modality, context, and intelligence lines that matter most on broad or multimodal work. Each leads on the one independent board that scores it and is absent from the other's, and neither has an independently verified SWE-bench Verified score — so that argument is a wash. And SpaceXAI's "Opus-class, much faster" framing stays a vendor claim until independent latency benchmarks land. If your work is output-heavy generation, agentic coding, or anything that rewards the cheapest output rate — pick Grok 4.5. If your work is multimodal, very-long-context, or Google-native — pick Gemini 3.1 Pro. For most teams the rational endgame is routing by workload, because each model answers a question the other cannot. For the models one step away from this matchup, see our Grok 4.5 review, our Gemini 3.1 Pro review, our Claude Opus 4.8 review for the model Grok is measured against, and our related comparisons: Claude Opus 4.8 vs Gemini 3.1 Pro, Claude Sonnet 5 vs Gemini 3.1 Pro, and Claude Fable 5 vs Gemini 3.1 Pro.
Sources
Every figure in this comparison is attributed to a primary or independent source. Pricing and specifications come from the vendors' own documentation; capability scores come from independent third parties; vendor claims are labeled as such throughout.
- SpaceXAI — Grok 4.5 model documentation, specifications, and API pricing
- SpaceXAI (xAI) — Grok 4.5 announcement and positioning
- Google — Gemini API pricing (context-length tiers, verified)
- Google — Gemini 3.1 Pro model documentation
- Google DeepMind — Gemini 3.1 Pro model card (self-reported benchmarks)
- Artificial Analysis — Intelligence Index and AA-Omniscience and the Artificial Analysis Coding Agent Index (v1.3, read August 2, 2026)
- LMArena — human-preference Elo leaderboard
- vals.ai — SWE-bench Verified independent leaderboard
Last compared: July 2026. Grok 4.5 reached general availability on July 9, 2026, and in the European Union on July 17, 2026; Gemini 3.1 Pro has been Google's deployed flagship since February 2026 and still carries a Preview label. Both models are moving fast, and we will revise this comparison as independent benchmark coverage matures.
Our Verdict
A split verdict between SpaceXAI's aggressively priced flagship and Google's multimodal flagship, with no single overall winner. Where Grok 4.5 leads: $6 per million output tokens that is half of Gemini's $12 up to 200,000 tokens, with Grok's $12 above that band two-thirds of Gemini's $18; the independent Artificial Analysis Coding Agent Index v1.3 at 64.4 against 30.3 for Gemini 3.1 Pro; and general availability since July 9, 2026. Where Gemini 3.1 Pro leads: native multimodal input across text, image, video, audio, and PDF, where Grok takes only text and image; a marginally higher Artificial Analysis Intelligence Index of 57 against 54; a charted LMArena Elo of 1485, where Grok is not charted; double the context window at 1,000,000 tokens against 500,000; cheaper cached-input reads at $0.20 per million against Grok's $0.30; and availability in the European Union, where Grok 4.5 is not offered under the EU AI Act's systemic-risk designation. Input price is level at the standard band ($2 per million each). Neither model has an independently verified SWE-bench score: Grok 4.5 is too new to appear on vals.ai, and Gemini's 80.6 percent is self-reported on DeepMind's model card. Artificial Analysis also flags a 54 percent hallucination rate for Grok 4.5 on its AA-Omniscience index, a documented reliability caution, and SpaceXAI's 'Opus-class, much faster' framing is a vendor claim pending independent latency benchmarks. Best for cheap output and coding value outside the EU: Grok 4.5. Best for native multimodal input, aggregate intelligence, long context, and EU availability: Gemini 3.1 Pro. Route output-heavy generation and agentic coding to Grok, and multimodal, very-long-context, Google-native, and EU-bound work to Gemini 3.1 Pro.
Choose Grok 4.5
SpaceXAI's reasoning model — Opus-class speed at $2 and $6 per million tokens, 500K context, available to EU users since July 17, 2026; succeeded by Grok 4.6 on August 12.
Try Grok 4.5 →Choose Gemini 3.1 Pro Preview
Google DeepMind's flagship Gemini 3.1 Pro Preview — 94.3% GPQA Diamond, 77.1% ARC-AGI-2, 1M-token context, multimodal in/text out, vibe coding plus agentic tool use. Preview status as of April 2026.
Try Gemini 3.1 Pro Preview →Frequently Asked Questions
Is Grok 4.5 better than Gemini 3.1 Pro Preview?
A split verdict between SpaceXAI's aggressively priced flagship and Google's multimodal flagship, with no single overall winner. Where Grok 4.5 leads: $6 per million output tokens that is half of Gemini's $12 up to 200,000 tokens, with Grok's $12 above that band two-thirds of Gemini's $18; the independent Artificial Analysis Coding Agent Index v1.3 at 64.4 against 30.3 for Gemini 3.1 Pro; and general availability since July 9, 2026. Where Gemini 3.1 Pro leads: native multimodal input across text, image, video, audio, and PDF, where Grok takes only text and image; a marginally higher Artificial Analysis Intelligence Index of 57 against 54; a charted LMArena Elo of 1485, where Grok is not charted; double the context window at 1,000,000 tokens against 500,000; cheaper cached-input reads at $0.20 per million against Grok's $0.30; and availability in the European Union, where Grok 4.5 is not offered under the EU AI Act's systemic-risk designation. Input price is level at the standard band ($2 per million each). Neither model has an independently verified SWE-bench score: Grok 4.5 is too new to appear on vals.ai, and Gemini's 80.6 percent is self-reported on DeepMind's model card. Artificial Analysis also flags a 54 percent hallucination rate for Grok 4.5 on its AA-Omniscience index, a documented reliability caution, and SpaceXAI's 'Opus-class, much faster' framing is a vendor claim pending independent latency benchmarks. Best for cheap output and coding value outside the EU: Grok 4.5. Best for native multimodal input, aggregate intelligence, long context, and EU availability: Gemini 3.1 Pro. Route output-heavy generation and agentic coding to Grok, and multimodal, very-long-context, Google-native, and EU-bound work to Gemini 3.1 Pro.
Which is cheaper, Grok 4.5 or Gemini 3.1 Pro Preview?
Grok 4.5 starts at $2 in / $6 out per M tokens. Gemini 3.1 Pro Preview starts at $2 in / $12 out per M tokens. Check the pricing comparison section above for a full breakdown.
What are the main differences between Grok 4.5 and Gemini 3.1 Pro Preview?
The key differences span across 18 features we compared. For API input price (per million tokens), Grok 4.5 offers $2.00 up to 200K, $4.00 above 200K (verified) while Gemini 3.1 Pro Preview offers $2.00 up to 200K, $4.00 above 200K (verified). For API output price (per million tokens), Grok 4.5 offers $6.00 up to 200K, $12.00 above 200K (verified) while Gemini 3.1 Pro Preview offers $12.00 up to 200K, $18.00 above 200K (verified). For Cached input price (per million tokens), Grok 4.5 offers $0.30 up to 200K, $0.60 above 200K (verified) while Gemini 3.1 Pro Preview offers $0.20 up to 200K, $0.40 above 200K (verified). See the full feature comparison table above for all details.